

Web Crawling vs. Web Scraping: A Practical Guide with Examples

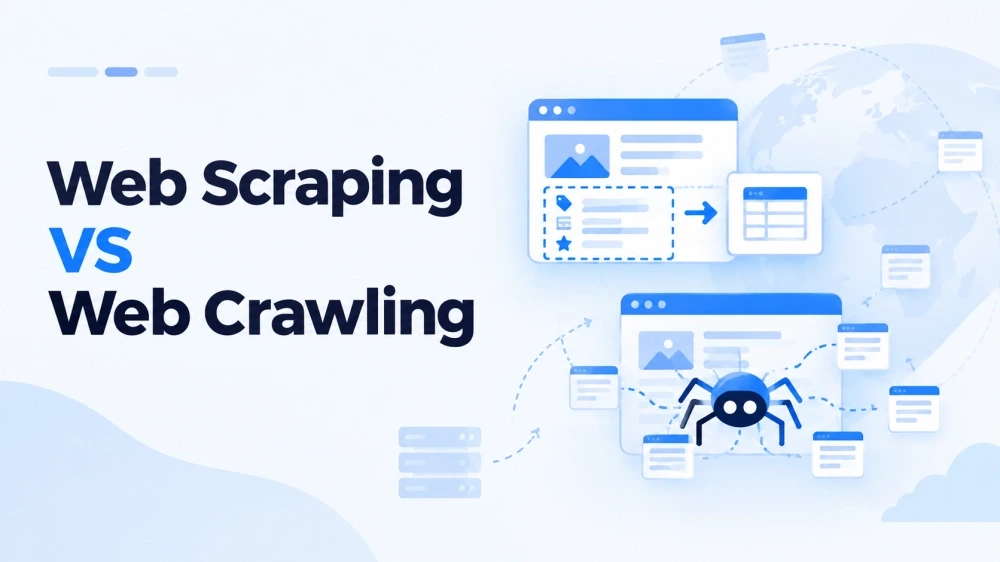
Imagine you want to track laptop prices across a dozen online stores. Before you can grab a single price, you need to find every product page worth checking. That's web crawling. Then you extract the model name, price, and stock status from each page. That's web scraping. They sound similar and are often confused, but they serve 2 different purposes. Most real-world projects use both. Keep reading to learn how to tell them apart and put them to work.
What Is Web Crawling? (Link Discovery & Indexing)
Web crawling is the process of discovering, visiting, and navigating pages on the web. A crawler, also called a spider or a bot, starts with a list of seed URLs. It loads each page and follows the links on it to discover new pages. Then it visits those pages and follows their links too. Step by step, the crawler builds a map of connected pages.
A crawler typically keeps a queue of URLs waiting to be visited. It fetches each page, extracts its links, and adds new URLs to the queue. It can also check rules such as robots.txt to determine which pages it should crawl. Search engines use crawlers like Googlebot to discover web pages and gather information that may be used to build their search indexes. Over time, a crawler can discover a large number of pages across a website or the wider web, depending on its scope, configuration, and crawling rules.
What Is Web Scraping? (Extracting Structured Data)
Web scraping extracts specific data from web pages and saves it in a structured format. You point a scraper at a page and tell it what to collect. It might grab product names, prices, reviews, or any other fields you choose. The scraper retrieves the page content, extracts the data you need, and organizes it into a format you can use, such as a spreadsheet or database.
A scraper fetches a web page or loads it in a browser if needed, then collects specific information, such as a product's name, price, and stock status. It cleans the scraped data by removing duplicates, standardizing formats, and handling missing values. Finally, it saves the scraped data in a structured format, for example, a spreadsheet, CSV file, or database. Some websites offer official APIs that provide data directly, but scraping is an alternative when no suitable API is available, or the API doesn't provide the data you need.
💡Web Scraping vs. Parsing:
Web scraping focuses on collecting specific data from web pages.
Parsing interprets the page's HTML or other content so a program can identify and process its structure.
Parsing is often one step in a scraping workflow, but scraping covers the broader process of retrieving pages, extracting target data, and saving the results.
Web Crawling vs Web Scraping: Side-by-Side Comparison
Web crawling and web scraping often work together. Crawling finds the pages you need, while scraping extracts the specific information from those pages. If you already have the URLs, you can often scrape them directly without crawling first.
Comparison | Web Crawling | Web Scraping |
Main Goal | Discover web pages and follow links | Extract specific data from web pages |
How It Works | Visits pages, finds links, and follows them to discover more pages | Retrieves page content and collects the target data |
Starting Point | One or more seed URLs | A specific URL or a list of known URLs |
Scope | Broad, often covering a website or multiple websites | Targeted, focusing on specific pages and data fields |
Main Output | A list of URLs, a site map, or an index of discovered pages | Structured data, such as product names, prices, and stock status |
Typical Tools | Web crawlers and search engine bots, such as Googlebot | Web scraping scripts, browser automation tools, and scraping APIs |
Common Uses | Discovering website pages, building search indexes, and mapping site structures | Tracking product prices, collecting reviews, and gathering data for analysis |
Main Challenges | Managing large URL lists, avoiding duplicate pages and crawl traps, and respecting crawl rules | Handling changing page layouts, dynamic content, anti-bot measures, and inconsistent data |
Here's a closer look at how each process works, where it's commonly used, and how to tell them apart in practice.
Purpose and Goals
Web crawling is about discovery. Its goal is to find web pages and map how they connect through links. For example, a search engine crawls an online store to discover its product pages so they can be considered for inclusion in search results.
Web scraping is about extraction. Its goal is to collect specific data from those pages, such as product names, prices, and reviews. For example, a scraper can collect the price and stock status of each product to help you compare offers across different stores.
In simple terms, crawling finds the pages, while scraping collects the information on them.
Input and Output
Web crawling starts with one or more seed URLs, such as a website's homepage, and follows links to discover more pages. Its input is a starting list of URLs, and its output is a growing list of discovered URLs or a map of how pages connect.
Web scraping works with the content of specific web pages. It can use URLs discovered through web crawling or a list of URLs you already have. It retrieves the page content, extracts the information you need, and saves it as structured data. If you already know which pages to scrape, you don't need to run a crawler first.
Common Use Cases
Web crawling is useful when you need to discover pages across a website. Web scraping is useful when you need specific information from web pages. Here is the difference at a glance:
Web Crawling
SEO: Visit website pages and follow internal links to audit site structure and find broken links.
E-commerce: Discover product pages across online stores.
Market Research: Find relevant pages across industry websites.
Lead Generation: Discover relevant company profiles and business directory pages.
Brand Monitoring: Discover pages on selected websites that may contain brand-related content.
Web Scraping
SEO: Extract page titles, meta descriptions, and other SEO data for bulk analysis.
E-commerce: Collect product names, prices, and stock status to compare competitors and track price changes.
Market Research: Gather product features, pricing, and publicly available market data for comparison.
Lead Generation: Collect publicly available company names, website URLs, and other relevant business information where permitted.
Brand Monitoring: Extract brand mentions, product reviews, and customer feedback to monitor brand reputation.
Web Scraping vs. Web Crawling in Python
Python is widely used for both web crawling and web scraping. For crawling, developers often use Scrapy to discover and visit pages by following links. For scraping, they commonly use Requests to fetch page content and Beautiful Soup to extract specific data. Playwright is another option when a page requires a browser to load its content.
Using the same e-commerce website as an example, the following code snippets show how to find product URLs and extract product details.
Example 1: Web Crawling with Python
Suppose you want to find product pages across an online store. This simple example uses Requests and Beautiful Soup to collect product links from a category page.
import requests
from bs4 import BeautifulSoup
from urllib.parse import urljoin

url = "https://example.com/products"
response = requests.get(url, timeout=10)
response.raise_for_status()

soup = BeautifulSoup(response.text, "html.parser")

for link in soup.select("a.product-link"):
    href = link.get("href")
    if href:
        print(urljoin(url, href))
The script fetches the category page, finds product links, and prints their URLs. A full crawler would also visit discovered pages and follow additional links as needed.
Example 2: Web Scraping with Python
Now suppose you already have a product URL and want to check its price. This example extracts the product name and price from that page.
import requests
from bs4 import BeautifulSoup

url = "https://example.com/products/laptop"
response = requests.get(url, timeout=10)
response.raise_for_status()

soup = BeautifulSoup(response.text, "html.parser")

name = soup.select_one("h1.product-name")
price = soup.select_one(".product-price")

print("Product:", name.get_text(strip=True) if name else "Not found")
print("Price:", price.get_text(strip=True) if price else "Not found")
The script extracts specific product details instead of discovering additional pages. The URLs and CSS selectors are placeholders, so you would need to replace them with values that match the target website's actual HTML.
How Crawling and Scraping Work Together
Most real-world projects combine crawling and scraping into a single workflow. First, a crawler discovers relevant pages. Then, a scraper extracts the data from each page. For example, a price tracker can crawl an online store's category pages to find product URLs, then scrape each product page for its name, price, and availability.
The same approach works for a news aggregator. A crawler discovers newly published article URLs, and a scraper extracts the headline, author, and article text. Crawling finds the pages, while scraping turns their content into structured data. Together, they create a complete data collection pipeline.
Common Challenges: IP Blocking, CAPTCHA & Anti-Bot
Once you start collecting data at scale, you may run into another problem: websites blocking your requests. Anti-bot systems may flag automated traffic and respond with CAPTCHAs, request throttling, or IP bans. Sending too many requests in a short time, repeating the same actions, or accessing pages too frequently can increase the risk of being blocked. These restrictions can interrupt data collection and make large-scale projects harder to maintain.
Proxies can help by routing requests through different IP addresses instead of sending them all from one IP. This gives crawlers and scrapers more flexibility when collecting data at scale and can reduce the risk of IP-based blocks. Since websites vary in how they handle automated traffic, choosing a trusted proxy provider with suitable IP types and reliable connections is an important part of setting up your crawling or scraping workflow.
Choosing a Proxy Provider for Web Scraping and Crawling
If you're running a web crawling or scraping project, the right proxy setup can help you manage IP-based blocks and keep data collection running more smoothly. IPcook is an affordable proxy provider offering residential, unlimited residential, ISP, and datacenter proxies to support different data collection needs.
IPcook Residential Proxies give you access to a pool of 55M+ real residential IPs across 185+ countries, with free country- and city-level targeting. You can choose rotating or sticky sessions from 1 minute to 24 hours. They're a strong starting point for collecting data from e-commerce and other sites with stricter anti-bot defenses.
For projects that need to collect data across large numbers of pages, IPcook Unlimited Proxies offer unlimited traffic at a fixed price of $350 for 30 days, with 100 Mbps bandwidth. Higher bandwidth and longer plans are also available. If your scraping workflow needs a stable IP across requests, IPcook ISP Proxies offer unlimited traffic and IPs across 8 major countries, which you can mix in a single order. IPcook Datacenter Proxies provide a lower-cost option for high-volume collection on sites with lighter restrictions.
Other Key Features of IPcook:
HTTP and SOCKS5 Support: Supports both protocols for compatibility with a wide range of crawling and scraping tools.
One-line API Integration: Residential proxies can be assigned with a single line of API code, making it easier to deploy proxies in automated scripts.
Team Management: Residential proxies support up to 10 free subaccounts. It's easier to manage access and divide tasks across a team.
Easy Scrapy Integration: Configure IPcook proxies directly in Scrapy's settings to route requests through dynamic residential IPs without complicated setup.
Quick Setup Guides: Get started in 3 simple steps with detailed setup instructions and video tutorials.
24/7 Customer Support: Get help around the clock through multiple channels, including live chat, email, and phone.
The Bottom Line
Crawling and scraping are 2 different jobs that usually run side by side, but most data collection projects need both. Crawling helps you discover the right pages, while scraping extracts the information you need. Choose your tools based on whether you need to find URLs, collect data, or do both.
When you scale up, IP blocks and anti-bot systems can interrupt your workflow. IPcook provides residential, unlimited residential, ISP, and datacenter proxies to support your existing crawling and scraping tools. Choose a setup that fits your target websites, traffic needs, and budget to keep your data collection running more smoothly.
FAQs
Is ChatGPT a web crawler?
No. ChatGPT is an AI assistant, not a standalone web crawler. It can search the web or retrieve specific pages when needed, while OpenAI also operates separate crawlers for tasks such as making websites discoverable in ChatGPT Search. These systems have different roles and should not be confused.
Does WebCrawler still exist?
Yes. WebCrawler, launched in 1994, still operates as a search engine. It has historically used a metasearch model, combining results from other search engines rather than functioning as a general-purpose crawling framework. If you're looking to build your own data collection workflow, you'll need a separate crawling tool.
Is web crawling illegal?
Not automatically. Legality depends on factors such as the data collected, the method of access, applicable laws, and how the data is used. Copyright, privacy, contractual terms, and access restrictions may all matter. Review the rules that apply to your project, and seek legal advice when handling sensitive data or uncertain cases.
Is web scraping outdated?
No. Scraping keeps growing because public data keeps growing. Businesses still scrape for prices, leads, and market research. What changed is that modern scraping relies on proxies and careful pacing to stay unblocked. The technique is not outdated, but the tools have matured.
- What Is Web Crawling? (Link Discovery & Indexing)
- What Is Web Scraping? (Extracting Structured Data)
- Web Crawling vs Web Scraping: Side-by-Side Comparison
- Web Scraping vs. Web Crawling in Python
- How Crawling and Scraping Work Together
- Common Challenges: IP Blocking, CAPTCHA & Anti-Bot
- Choosing a Proxy Provider for Web Scraping and Crawling
- The Bottom Line
- FAQs