
Is Web Scraping Legal? Laws, Risks, and Best Practices

You may be preparing to scrape data from websites to collect product prices, customer reviews, or market data but still have important questions: Is Web Scraping Legal? Can the website take action against you? Are you allowed to use the results in a commercial project? There is no universal answer. Whether web scraping is legal usually depends on what data you collect, how you access it, how you use it, and which laws apply.
This guide explains the main legal risks behind web scraping, the relevant rules in the United States, the European Union, and the United Kingdom, and the practical steps that can help you build a more responsible data collection process.
📢Legal Disclaimer: This article provides general information about web scraping laws and risks, not legal advice. If your project involves personal data, protected content, restricted access, or commercial use, consult a qualified legal professional.
Is Web Scraping Legal?
Web scraping is not inherently illegal. It is a form of data scraping that involves collecting information from websites, and its legality generally depends on what data you collect, how you access it, and how you use it. Scraping publicly accessible factual data generally carries lower risk. However, public visibility does not mean the data can be collected or reused without limits.
To get a clearer sense of where your project stands, consider these three general risk levels:
Lower risk: Collecting factual information from public pages without logging in, using reasonable request rates, and limiting collection to data necessary for a legitimate purpose.
Higher risk: Collecting personal data or substantial amounts of copyrighted content, scraping behind a login, bypassing technical restrictions, or republishing and reselling protected content substantially unchanged.
Professional review recommended: Building a large commercial database, transferring personal data across jurisdictions, collecting training data for AI models, or continuing to scrape after receiving a cease-and-desist letter.
These categories are not guarantees of legality. A scraping activity may fall outside criminal computer-access laws yet still breach a contract, lead to a civil lawsuit, infringe privacy or copyright rights, or result in account suspension and IP blocking.
🌐Collecting Authorized Public Data at Scale: Once you have confirmed that you may access the target pages, a residential proxy can help you collect public data across different markets. IPcook Residential Proxies offers 55M+ residential IPs across 185+ countries, providing broad geographic coverage for regional data collection. Explore a residential proxy plan suited to your project.
What Makes Web Scraping Legal or Illegal?
Legal risk should be assessed across the entire scraping process, from selecting the source material to collecting and using the data. Changes at any stage can affect the legal assessment, even when scraping the same website.
The Data You Collect
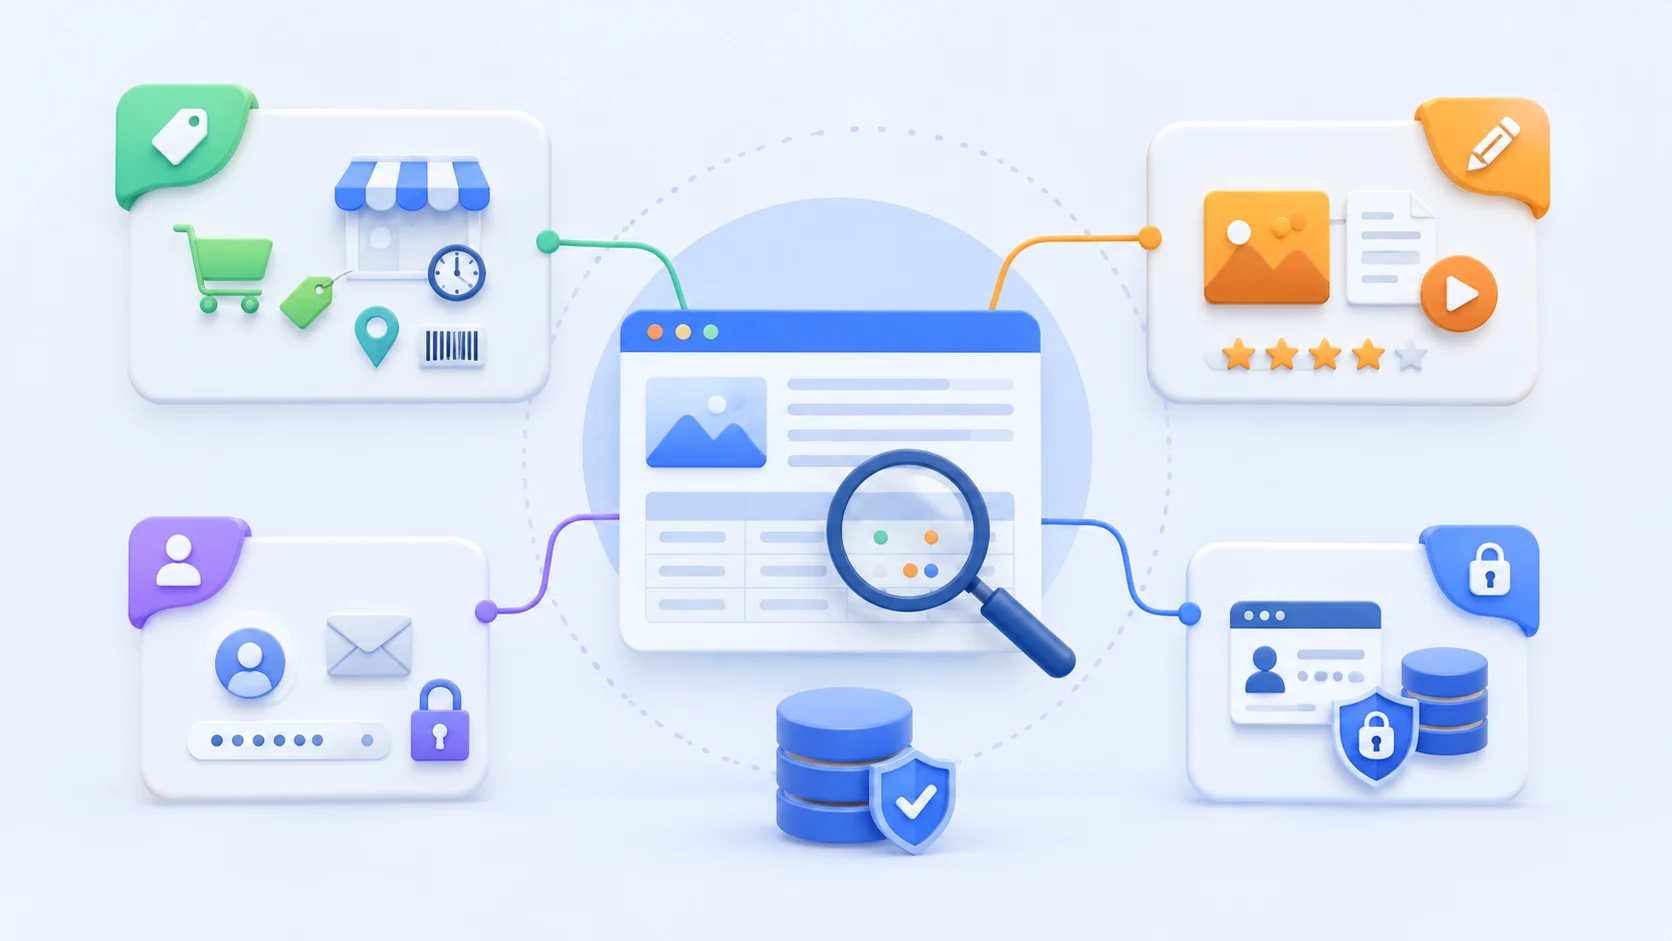
Not all website data receives the same legal protection. Before scraping, identify which of the following categories your project involves:
Factual data: Prices, business hours, addresses, and product numbers are generally not protected by copyright. For example, projects that scrape eBay product data may collect publicly available prices, product names, item numbers, and other factual listing information. However, the selection or arrangement of an entire database may qualify for separate protection.
Creative content: Articles, photographs, videos, user reviews, and original page designs may be copyrighted, limiting how they can be copied, stored, or reused.
Personal data: Names, email addresses, IP addresses, locations, and social media profiles may remain subject to privacy rules even when displayed publicly. This is relevant to projects involving platforms such as Instagram and TikTok, where public information may still include personal data.
Confidential or restricted data: Information available only after logging in, paying, or receiving specific permission usually presents greater risk than content open to everyone.
Publicly visible personal information is not automatically free to collect or use. Limit a project to the data it genuinely needs: a price comparison tool may require product names and prices, but not a seller’s personal contact details. Personal data should also be retained only as long as necessary for the stated purpose, reflecting the principles of data minimization and storage limitation.
The Way You Access It
How you reach the data matters as much as whether it appears online. A page open to anyone without an account generally presents fewer access-related concerns than content available only after signing in, accepting specific terms, or paying a fee. Trying to bypass CAPTCHAs, authentication, paywalls, or other clear access controls carries greater risk. Continuing after an account ban, formal warning, or cease-and-desist letter can make the dispute more serious. Technical access alone does not establish legal authorization.
Request volume matters too. Even when the data is public, a scraper that sends too many requests at once may slow the website, raise its operating costs, or interfere with normal service. That activity may violate site rules and lead to claims involving system interference or damage. Using moderate request rates and responding to clear access restrictions can reduce these risks.
How You Use Data
Legal concerns do not end once the data has been collected. A dataset used privately for research may present a different risk from the same information republished in a paid product or used to replace the source website. Common uses include:
Internal analysis and research: Usually less likely to compete with the source, particularly when only necessary facts are retained.
Price comparison, market research, and search tools: May create new value, but the risk depends on the amount of content copied and whether the service substitutes for the original website.
Commercial databases: Scale, licensing, data type, and competition with the source can all affect the legal assessment.
Republication or resale: Reproducing complete articles, images, reviews, or listings with little change may raise copyright and other legal concerns.
AI model training: The use of scraped copyrighted works for training remains legally contested and requires a careful review of the source material, access rights, and intended model use.
Web scraping for commercial use is not automatically illegal, just as research or internal use is not automatically permitted. Creating new analysis from factual data may reduce some copyright concerns, but transformative use is only one part of a broader fair-use assessment. It does not remove privacy, contract, or access-related obligations.
Web Scraping Laws by Region
Web scraping is not governed by a single global standard. The laws that apply may depend on where your business operates, where the target website is based, and where the people represented in the data live. The table below provides a quick comparison before each region is examined in more detail.
Region | Main Rules | Key Questions |
United States | CFAA, copyright law, state privacy laws, and contract law | Was the data accessed without authorization, was protected content copied, or were enforceable terms breached? |
European Union | GDPR, Database Directive, and DSM Directive | Does the dataset contain personal data, is there a lawful basis for processing it, or are database and copyright rights involved? |
United Kingdom | UK GDPR, Data Protection Act 2018, Copyright, Designs and Patents Act 1988, and Computer Misuse Act 1990 | Is personal data processed lawfully, was a protected area accessed, or was copyrighted material reused? |
Web Scraping Laws in the US
The United States has no single law governing web scraping. Legal disputes may involve the Computer Fraud and Abuse Act (CFAA), copyright law, contract law, and state privacy laws. The CFAA is particularly relevant when a scraper accesses parts of a website without authorization.
One important example is hiQ Labs v. LinkedIn. The Ninth Circuit found that collecting data from public LinkedIn profiles likely did not violate the CFAA because anyone could view the profiles without passing through an authorization gate. However, the ruling addressed only the CFAA’s access restrictions, not whether the scraping activity was lawful under other rules.
Web Scraping Laws in Europe and the UK
In the EU, scraping identifiable information may fall under the GDPR, even when it comes from public pages. A lawful basis is still required, and only necessary data should be collected. The Database Directive and DSM Directive may also restrict the systematic extraction of database content or copyrighted works.
The UK has a similar but separate framework under the UK GDPR, Data Protection Act, copyright law, and Computer Misuse Act. Public pages and access-restricted areas are treated differently, but public availability does not remove privacy, copyright, or database-related obligations.
How Websites Restrict Web Scraping
Websites may use both written rules and technical controls to manage automated access. Before scraping, check which pages may be accessed, how the collected data may be used, and whether request limits apply.
Restriction | What to check | What does it mean for scraping |
Website terms | Rules on scraping, copying, or commercial use | Violations may lead to contract disputes |
robots.txt | Paths marked as disallowed | Indicates where crawlers are not welcome |
API rules | Rate limits, permitted uses, and retention rules | Exceeding them may violate API terms |
Login or paywall | Whether an account or payment is required | The content is not ordinarily public |
CAPTCHA or IP blocks | Active attempts to stop automated requests | Circumvention increases legal risk |
Cease-and-desist letter | A direct demand to stop scraping | Continuing may escalate the dispute |
These restrictions do not all carry the same legal weight. Website and API terms may create contractual obligations, while robots.txt mainly communicates a site’s crawler preferences. Login barriers, technical blocks, and direct requests to stop can provide clearer notice that access is restricted. If any restriction applies, pause and reassess the project before continuing.
How to Scrape Data Legally and Responsibly
A responsible scraping process starts before the first request is sent. Use an official API, open dataset, or written permission when available, then review the remaining risks in a consistent order:
Confirm access: Check that the pages are public and look for an official API or authorized data channel.
Limit the data: Exclude unnecessary personal data, copyrighted material, and restricted information.
Review site rules: Read the website terms,
robots.txt, API policies, and access requirements.Define the purpose: Pay closer attention to commercial use, republication, resale, and AI training.
Control requests: Set reasonable rates, concurrency, retries, and conditions that stop the scraper.
Keep records: Document sources, collection dates, legal reasoning, retention periods, and deletion rules.
Seek legal review: Consult a qualified professional for high-risk or cross-border projects.
Once access has been confirmed, proxies route scraping requests through different IP addresses and locations, helping collect location-specific data and distribute larger workloads across multiple connections. For scraping projects that require high anonymity and precise regional targeting, IPcook Residential Proxies automatically rotate residential IPs and offer country- and city-level targeting for collecting regional prices, product availability, and other localized public data.
For faster, high-volume collection that does not require residential IPs, IPcook Datacenter Proxies are a better fit. Both options integrate with existing scraping programs, while the IPcook dashboard helps teams monitor traffic, connection status, and usage.
Final Thoughts
Web scraping is not automatically illegal, but responsible data collection requires more than simply checking whether a page is publicly accessible. Review applicable laws and website rules, minimize the data you collect, respect access restrictions, and keep your collection practices proportionate to your purpose.
For ongoing or large-scale scraping, choose tools that fit your collection requirements and compliance needs. Explore IPcook Web scraping proxy solutions to support your data collection workflow!